Mix3R site icon Mix3R: Zero-shot Interactive 3D Scene Reconstruction from a Single Image in Mixed Reality

1 KAIST 2 La Trobe University
IEEE Transactions on Visualization and Computer Graphics (TVCG) 2026
TL; DR

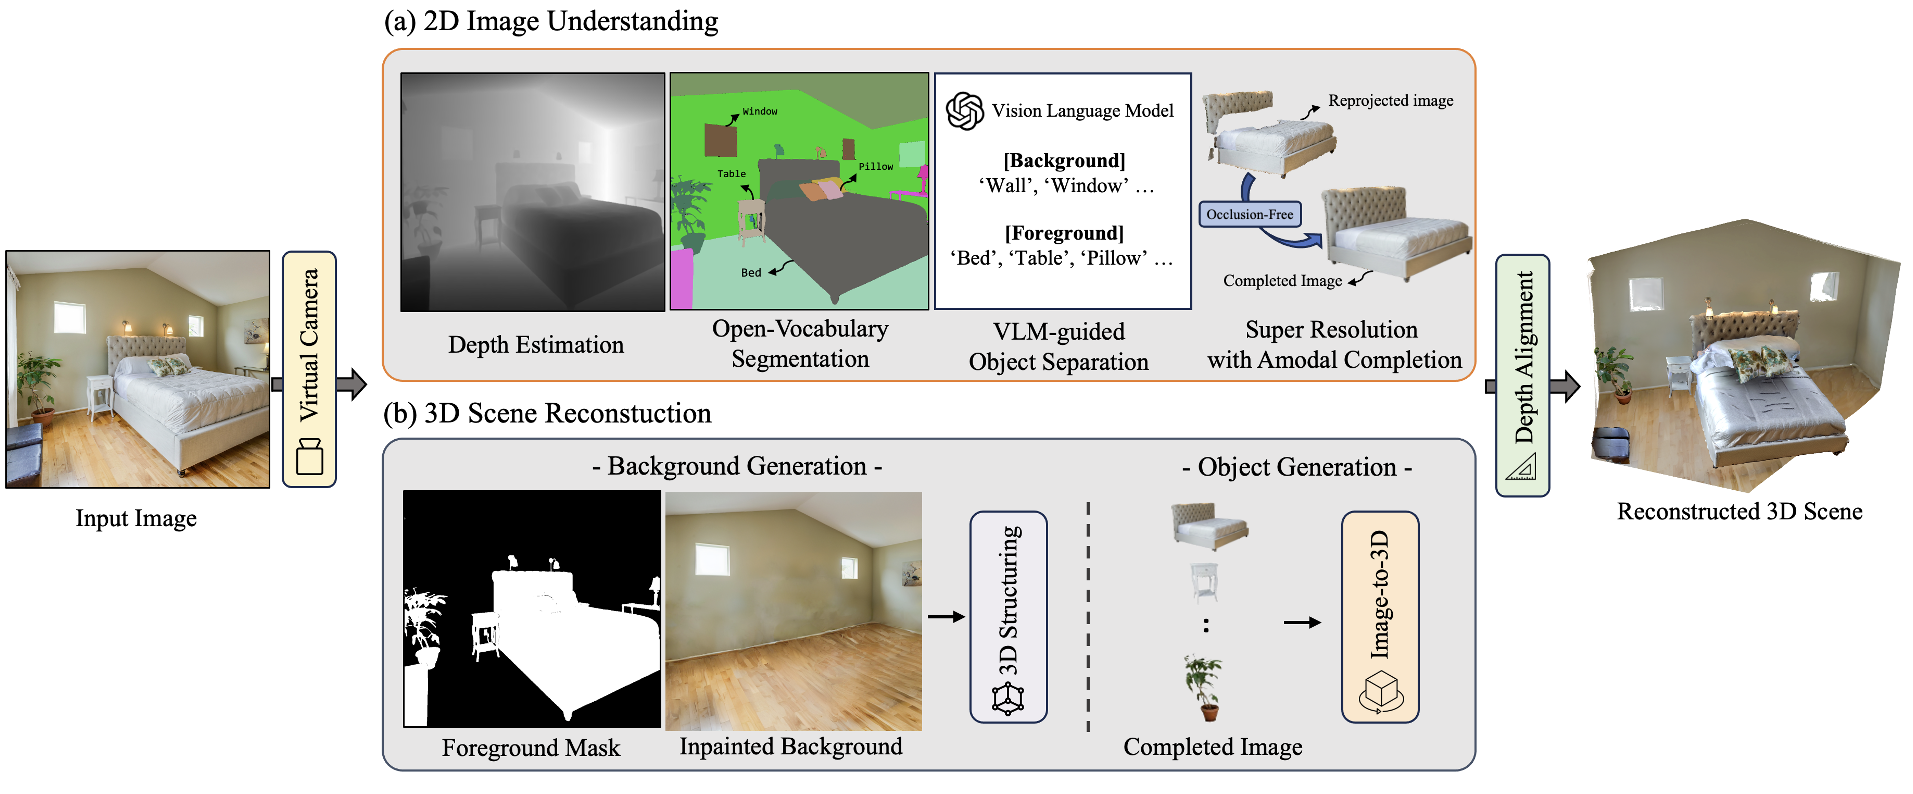
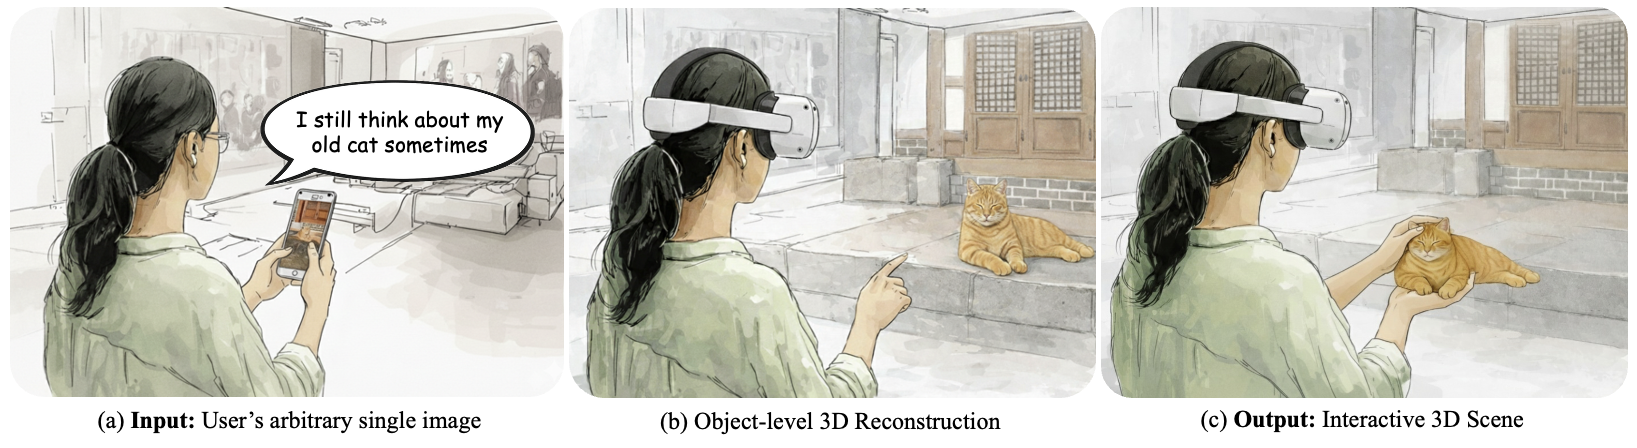
We introduce Mix3R, a training-free framework that reconstructs interactive 3D scenes robust to occlusions from a single RGB image by strategically integrating large-scale model priors.

Mix3R TLDR diagram

Abstract

We present Mix3R, a training-free 3D scene reconstruction frame work that enables immersive Mixed Reality (MR) interaction from a single real-world image. Despite recent progress in single-image 3D scene generation, existing methods often struggle with back ground recovery under occlusion and lack evaluations regarding natural interaction as well as immersion in MR environments. We address these challenges through a structured integration of large scale model priors, enabling geometrically consistent 3D scene reconstruction without additional training. The framework combines vision–language-guided foreground–background separation with depth alignment from back-projected point clouds to achieve reliable background completion while preserving detailed object geometry. Experiments on the 3D-FRONT dataset show that Mix3R improves reconstruction quality, reducing Chamfer Distance by over 23% and increasing object-level F-score by more than 6%, with additional gains in scene-level perceptual metrics. User studies on in-the-wild images further demonstrate higher user preference for the proposed method across diverse real-world scenes. These results indicate that our approach enables practical reconstruction of interactive MR spaces from a arbitrary single image.

Method

Mix3R method diagram

Overview of the Mix3R pipeline. (a) Given a single input image, our system performs depth estimation, open-vocabulary segmentation, VLM-guided foreground-background separation, and super-resolution with amodal completion for 2D image understanding. (b) The foreground mask is then used to inpaint the background, and each object image is converted into 3D and integrated with the background. Finally, depth alignment is applied to reconstruct a compositional 3D scene from the single input image.

Results

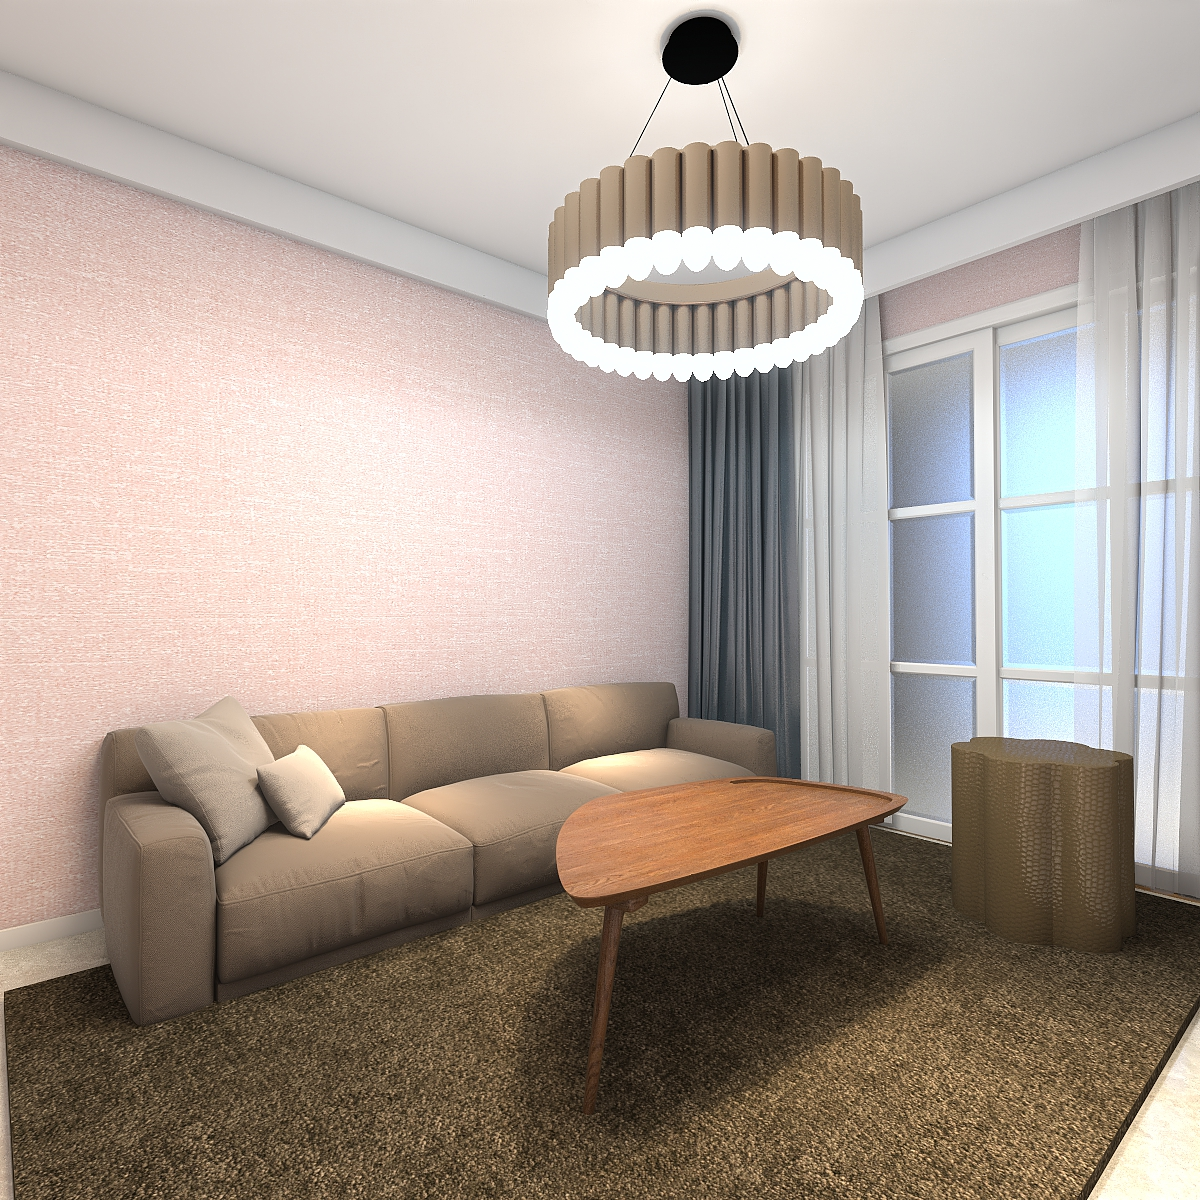
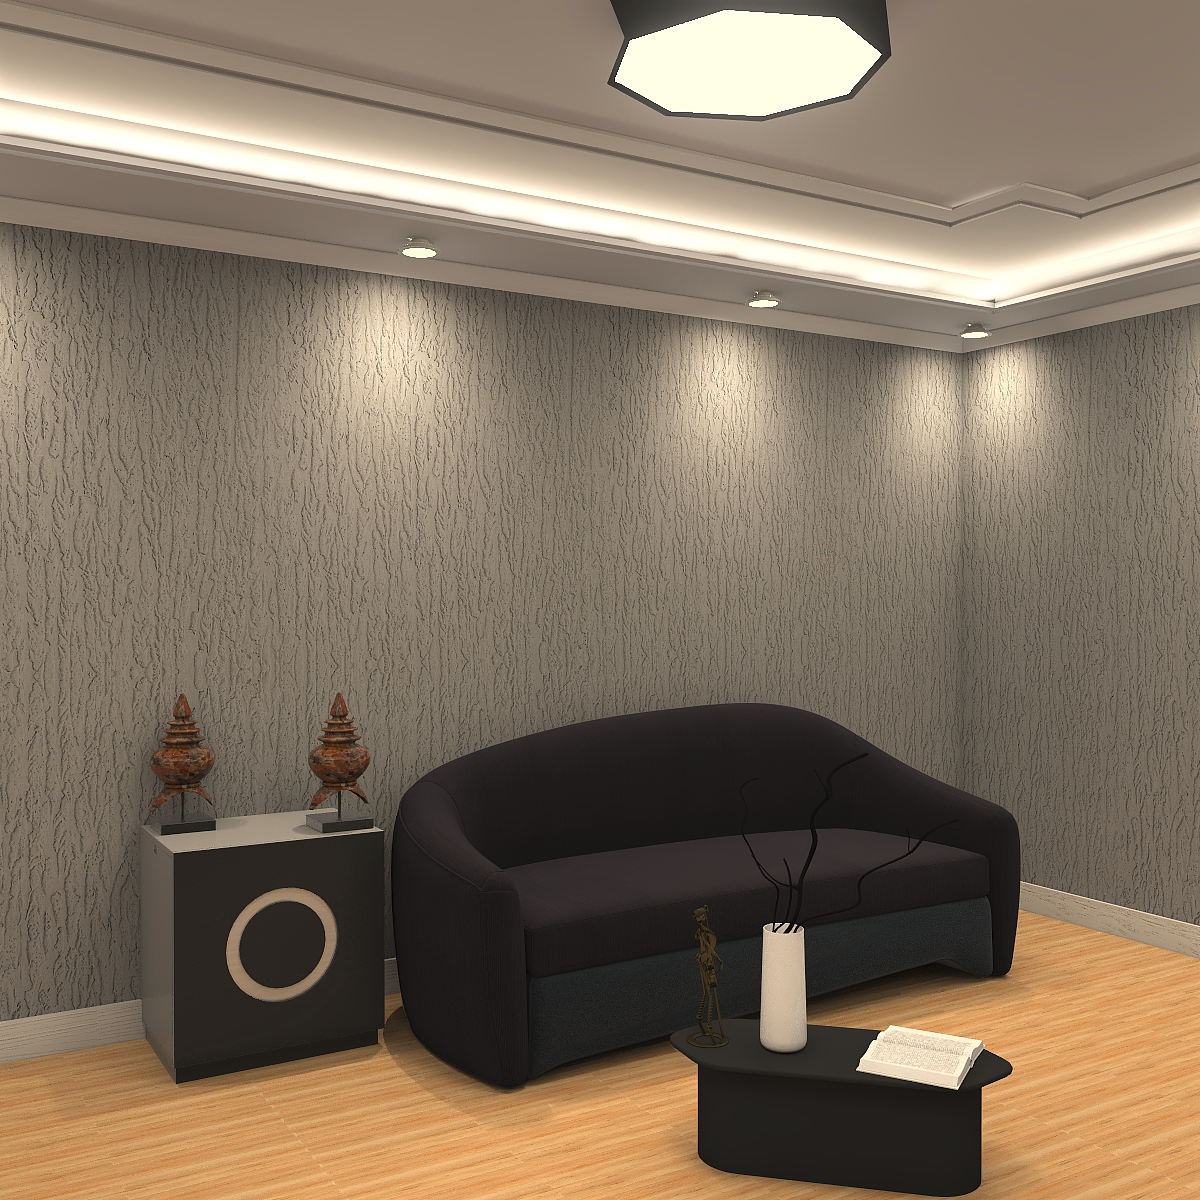
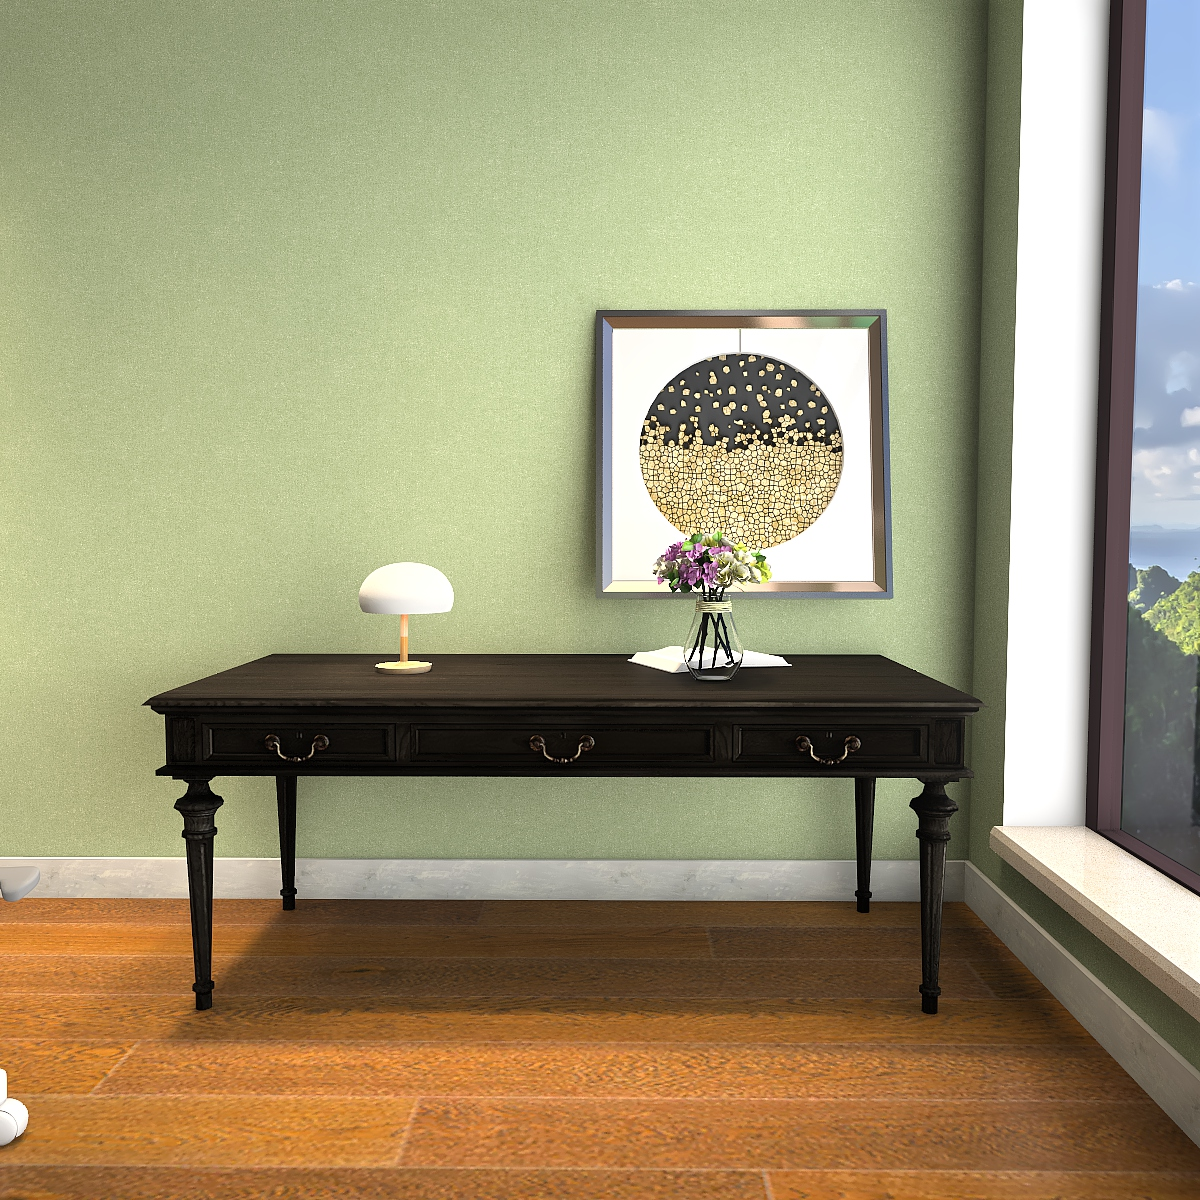
Interactive 3D Demos (3D-FRONT)

3D-FRONT demo image 1
3D-FRONT demo image 2
3D-FRONT demo image 3

Interactive 3D Demos (In-the-wild Image)

In-the-wild demo image 1
In-the-wild demo image 2
In-the-wild demo image 3

Demo Video